
جميع الكتب

مهني

1 Markets I: The Ecosystem and Exchange-Traded Marketsالأسواق عبر الإنترنت 2 Markets II: Rates, FX and Creditالأسواق عبر الإنترنت 3 Markets III: Commodities, Energy and Cryptoالأسواق عبر الإنترنت 4 Quantitative Methodsالأساليب عبر الإنترنت 5 Derivatives and Volatilityالمشتقات عبر الإنترنت 6 Rates, Credit, XVA and Riskالفائدة والائتمان والمخاطر عبر الإنترنت 7 Research Craft: Predictors, Backtests, Measurement, Portfoliosالبحث عبر الإنترنت 8 Strategies I: Equities and Futuresالاستراتيجيات عبر الإنترنت 9 Strategies II: Volatility, Relative Value, Macro and the Bank Desksالاستراتيجيات عبر الإنترنت 10 Microstructure and Executionالتنفيذ عبر الإنترنت 11 Market Making and High-Frequency Tradingصناعة السوق عبر الإنترنت 12 Machine Learning for Marketsتعلم الآلة عبر الإنترنت 13 Low-Latency Softwareالتكنولوجيا عبر الإنترنت 14 Networks, Hardware and Trading Infrastructureالتكنولوجيا عبر الإنترنت 15 Research, Data and Risk Platformsالتكنولوجيا عبر الإنترنت 16 The Desk and the Firmالشركة عبر الإنترنت 17 The Industry: Firms, Roles and Careersالمسارات المهنية عبر الإنترنت 18 The Interview Bookالمسارات المهنية عبر الإنترنت
التطبيقات حول المدرب تسجيل الدخول ابدأ القراءة

Quantitative Finance · المسرد

ما معنى Memorisation, anonymisation test؟

يُعرف أيضًا باسم: memorisation · anonymisation test

Definition 14.5 Machine Learning for Markets · الفصل 14 — Large Language Models in Finance

Memorisation is a model’s ability to reproduce specific training examples, including their outcomes, rather than a rule that generalises; language models memorise text seen even once (Carlini and co-authors, 2021). The anonymisation test replaces the identifiers in an input (company names, tickers, dates) by placeholders and measures how much the model’s accuracy falls: a model that reads the text loses little, a model that recalls the event loses its memory.
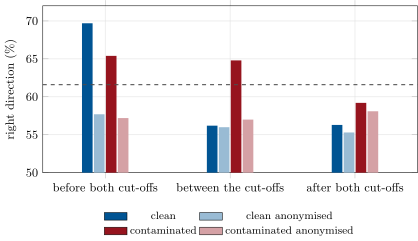
Share of headlines whose direction each model predicts correctly, by period, with names and weeks and with placeholders. The clean model’s training data end at the first cut-off, the contaminated model’s at the second. Dashed: the sign of the planted effect. Data: ml_llm.contamination.
Figure 14.2. Share of headlines whose direction each model predicts correctly, by period, with names and weeks and with placeholders. The clean model’s training data end at the first cut-off, the contaminated model’s at the second. Dashed: the sign of the planted effect. Data: ml_llm.contamination.
اقرأ في الفصل →