 Coach
Mixed-precision training runs the expensive operations (matrix products, convolutions) in a 16-bit format while keeping the weights, the loss and the optimiser’s state in 32 bits (Micikevicius and co-authors, 2018). bfloat16 is a 16-bit floating-point format with float32’s eight exponent bits and seven fraction bits: the same range as float32, and a machine epsilon (Book 4, chapter 25) of instead of , so no loss scaling is needed against underflow (Kalamkar and co-authors, 2019).
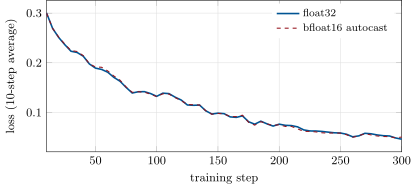
ml_train.run (fig_train.py).