
Todos os livros

Profissional

Apps Sobre Coach Entrar Começar a ler

Quantitative Finance · Glossário

O que é Model compilation?

Definition 26.2 Machine Learning for Markets · Capítulo 26 — Low-Latency Inference

Model compilation translates a trained model into code or data structures specialised for inference on a target (generated source, a flat array layout, a hardware description), removing the training framework from the prediction path (Asadi, Lin and de Vries, 2014; Lucchese and co-authors, 2015, for ranking forests).
Single-call latency of the same two models by execution path; 200 000 calls in C++ and Rust, 5 000 in Python (300 for the pure-Python forest), timed one by one. Measured on a laptop (Intel Core Ultra 7 155H) under WSL2 at low priority, no isolated cores; other jobs may have run. Data: bench_infer.py, measured_latency.csv.
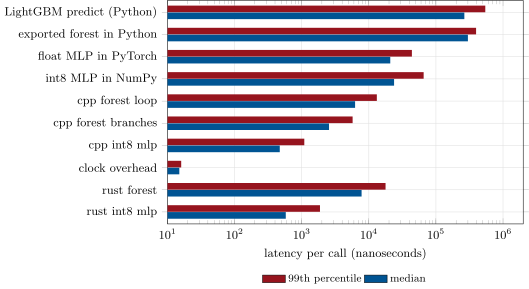
Figure 26.1. Single-call latency of the same two models by execution path; 200 000 calls in C++ and Rust, 5 000 in Python (300 for the pure-Python forest), timed one by one. Measured on a laptop (Intel Core Ultra 7 155H) under WSL2 at low priority, no isolated cores; other jobs may have run. Data: bench_infer.py, measured_latency.csv.
Ler no capítulo →