 Coach
A word embedding maps each word to a dense vector of a few dozen to a few thousand real numbers, learned so that words used in similar contexts get nearby vectors: by factorising a matrix of co-occurrence statistics, or by training a network to predict a word from its neighbours (Mikolov and co-authors, 2013).
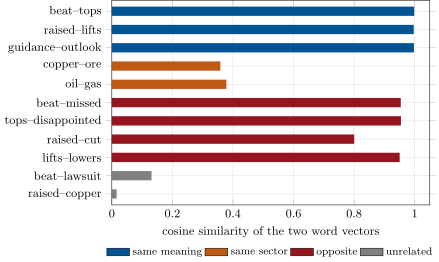
ml_text.pairs.