 Coach
An attention mechanism lets each position of a sequence form its output as a weighted average of all positions: with queries , keys and values computed from the sequence (), the output is . A transformer layer combines several attention heads, a position-wise network, residual connections and layer normalisation; positions are encoded by adding learned or fixed vectors to the inputs (Vaswani et al., 2017).
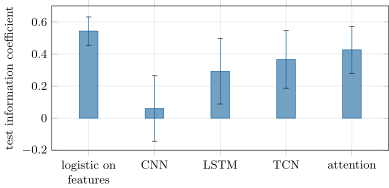
ml_lobseq.table.