 Coach
The classifier two-sample test trains a classifier to tell generated samples from real ones and reports its accuracy on held-out samples: 50% means the classifier cannot tell them apart (Lopez-Paz and Oquab, 2017). Train-on-synthetic test-on-real (TSTR) trains a downstream model on generated data and evaluates it on real data, comparing with the same model trained on real data (Esteban, Hyland and Rätsch, 2017).
| facts | two-sample | TSTR | TSTS | closer than | ||
| generator | passed | accuracy | IC | Sharpe | Sharpe | real (%) |
| real (train on real, test on real) | 6 | 0.545 | 0.078 | 0.86 | 5.0 | |
| block bootstrap | 6 | 0.491 | 0.062 | 0.71 | 1.19 | 14.5 |
| GARCH-t | 4 | 0.539 | 5.7 | |||
| VAE | 6 | 0.619 | 0.040 | 0.76 | 0.79 | 5.1 |
| GAN | 3 | 0.749 | 0.052 | 0.52 | 10.68 | 11.2 |
| diffusion | 4 | 0.693 | 0.030 | 0.23 | 1.45 | 1.4 |
ml_gen.judge.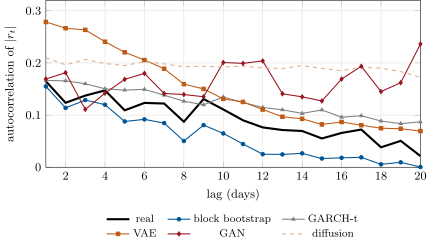
ml_gen.abs_acf.