
सभी किताबें

पेशेवर

ऐप्स परिचय Coach लॉग इन पढ़ना शुरू करें

Quantitative Finance · शब्दावली

Context switch, busy polling, kernel bypass क्या है?

अन्य नाम: context switch · busy polling · kernel bypass

Definition 13.5 Low-Latency Software · अध्याय 13 — Linux Tuning

A context switch is the kernel saving the state of the thread running on a CPU and restoring another’s; a thread that blocks waiting for data gives its CPU away and is switched back in when the data arrives. Busy polling checks for new data in a loop that never blocks, keeping the CPU. Kernel bypass moves the network card’s receive and transmit queues into the application’s address space, so that packets reach the program without a system call, an interrupt or the kernel’s network stack.
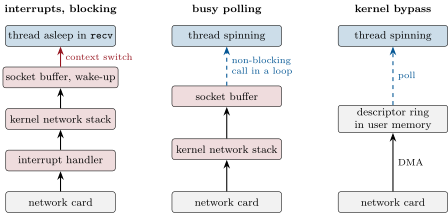
Three ways for a packet to reach a thread. Left: the card interrupts a CPU, the kernel processes the packet, and the sleeping thread is switched back in. Middle: the thread never sleeps and polls the socket. Right: the card writes into queues mapped into the program, which polls them; the kernel is not on the path (DMA: direct memory access, chapter 4). Shaded red: the kernel’s work on the path.
Figure 13.3. Three ways for a packet to reach a thread. Left: the card interrupts a CPU, the kernel processes the packet, and the sleeping thread is switched back in. Middle: the thread never sleeps and polls the socket. Right: the card writes into queues mapped into the program, which polls them; the kernel is not on the path (DMA: direct memory access, chapter 4). Shaded red: the kernel’s work on the path.
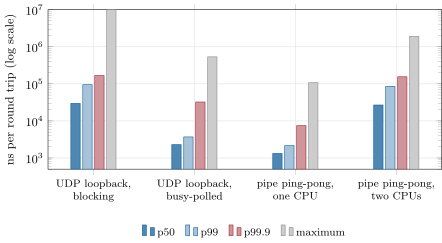
Round trips of 64 bytes between two pinned threads over loopback UDP, receiving with a blocking call or with non-blocking calls in a loop, and of one byte through two pipes with both threads on one CPU or on two; 100 000 round trips each. Measured on a laptop (Intel Core Ultra 7 155H) under WSL2, no isolated cores. Data: bench_tuning.py.
Figure 13.4. Round trips of 64 bytes between two pinned threads over loopback UDP, receiving with a blocking call or with non-blocking calls in a loop, and of one byte through two pipes with both threads on one CPU or on two; 100 000 round trips each. Measured on a laptop (Intel Core Ultra 7 155H) under WSL2, no isolated cores. Data: bench_tuning.py.
अध्याय में पढ़ें →