 Coach
Dropout sets each hidden unit to zero with probability during training, scaling the others by , and uses the full network at prediction. Batch normalisation standardises each hidden unit over the rows of the mini-batch (running averages at prediction); layer normalisation standardises the units of each row, independently of the batch.
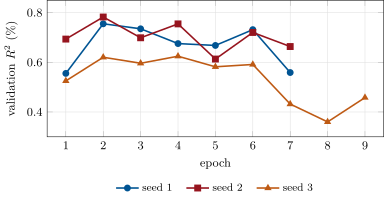
ml_nets.fitted.