 Coach
The exploration–exploitation trade-off is the choice between the action that looks best now and an action that teaches more. A multi-armed bandit is the MDP with one state: each round an arm is chosen and its reward drawn; the loss against always playing the best arm is the regret. A contextual bandit observes a context (the order, the market) before choosing, and learns a reward model per arm; its actions do not change future contexts.
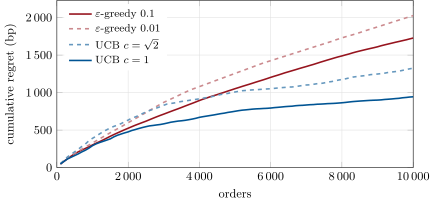
ml_rl.bandits.