 Coach
Clustering partitions objects into groups whose members are more similar to each other than to others, without labels. k-means chooses centres and assigns each object to the nearest, alternating the two steps to minimise the within-group sum of squared distances (Lloyd’s algorithm). Hierarchical clustering merges the closest groups step by step into a tree and cuts it at the desired number of groups; for assets the usual distance is between return series (Mantegna, 1999), the one behind hierarchical risk parity (Book 7, chapter 26).
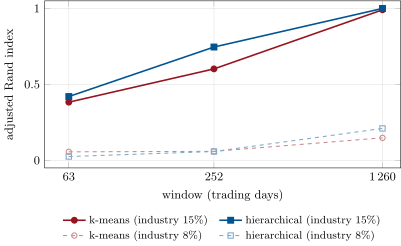
ml_regimes.clustering.