
جميع الكتب

مهني

1 Markets I: The Ecosystem and Exchange-Traded Marketsالأسواق عبر الإنترنت 2 Markets II: Rates, FX and Creditالأسواق عبر الإنترنت 3 Markets III: Commodities, Energy and Cryptoالأسواق عبر الإنترنت 4 Quantitative Methodsالأساليب عبر الإنترنت 5 Derivatives and Volatilityالمشتقات عبر الإنترنت 6 Rates, Credit, XVA and Riskالفائدة والائتمان والمخاطر عبر الإنترنت 7 Research Craft: Predictors, Backtests, Measurement, Portfoliosالبحث عبر الإنترنت 8 Strategies I: Equities and Futuresالاستراتيجيات عبر الإنترنت 9 Strategies II: Volatility, Relative Value, Macro and the Bank Desksالاستراتيجيات عبر الإنترنت 10 Microstructure and Executionالتنفيذ عبر الإنترنت 11 Market Making and High-Frequency Tradingصناعة السوق عبر الإنترنت 12 Machine Learning for Marketsتعلم الآلة عبر الإنترنت 13 Low-Latency Softwareالتكنولوجيا عبر الإنترنت 14 Networks, Hardware and Trading Infrastructureالتكنولوجيا عبر الإنترنت 15 Research, Data and Risk Platformsالتكنولوجيا عبر الإنترنت 16 The Desk and the Firmالشركة عبر الإنترنت 17 The Industry: Firms, Roles and Careersالمسارات المهنية عبر الإنترنت 18 The Interview Bookالمسارات المهنية عبر الإنترنت
التطبيقات حول المدرب تسجيل الدخول ابدأ القراءة

Quantitative Finance · المسرد

ما معنى Policy gradient, actor–critic method؟

يُعرف أيضًا باسم: policy gradient · actor--critic method

Definition 17.4 Machine Learning for Markets · الفصل 17 — Reinforcement Learning Foundations

A policy gradient method adjusts the parameters θ\theta of a stochastic policy in the direction E[Gt∇θlog⁡πθ(ut∣xt)]\E[G_t\nabla_\theta\log\pi_\theta(u_t\mid x_t)], the gradient of expected cumulative reward (REINFORCE; Williams, 1992); a baseline subtracted from GtG_t lowers the variance without biasing it. An actor–critic method replaces GtG_t by the temporal-difference error of a learned value function (the critic), so that the policy (the actor) learns at every step.
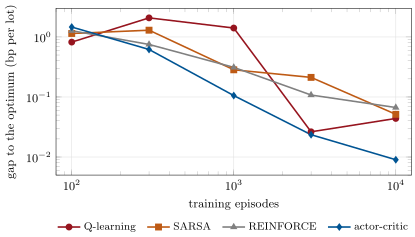
Value gap to the dynamic-programming optimum of the policy learned after a number of episodes (the greedy policy for Q-learning and SARSA, the softmax policy for the others), mean of three seeds. Data: ml_rl.learning_curves.
Figure 17.1. Value gap to the dynamic-programming optimum of the policy learned after a number of episodes (the greedy policy for Q-learning and SARSA, the softmax policy for the others), mean of three seeds. Data: ml_rl.learning_curves.
اقرأ في الفصل →