 Coach
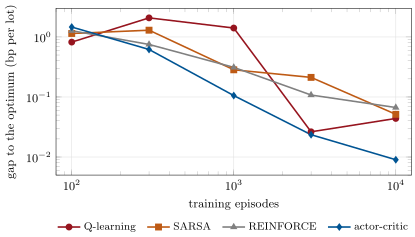
A policy gradient method adjusts the parameters of a stochastic policy in the direction , the gradient of expected cumulative reward (REINFORCE; Williams, 1992); a baseline subtracted from lowers the variance without biasing it. An actor–critic method replaces by the temporal-difference error of a learned value function (the critic), so that the policy (the actor) learns at every step.
ml_rl.learning_curves.