
Todos os livros

Profissional

Apps Sobre Coach Entrar Começar a ler

Quantitative Finance · Glossário

O que é Policy gradient, actor–critic method?

Também chamado de: policy gradient · actor--critic method

Definition 17.4 Machine Learning for Markets · Capítulo 17 — Reinforcement Learning Foundations

A policy gradient method adjusts the parameters θ\theta of a stochastic policy in the direction E[Gt∇θlog⁡πθ(ut∣xt)]\E[G_t\nabla_\theta\log\pi_\theta(u_t\mid x_t)], the gradient of expected cumulative reward (REINFORCE; Williams, 1992); a baseline subtracted from GtG_t lowers the variance without biasing it. An actor–critic method replaces GtG_t by the temporal-difference error of a learned value function (the critic), so that the policy (the actor) learns at every step.
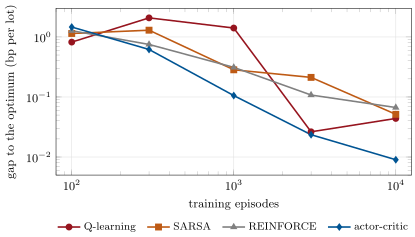
Value gap to the dynamic-programming optimum of the policy learned after a number of episodes (the greedy policy for Q-learning and SARSA, the softmax policy for the others), mean of three seeds. Data: ml_rl.learning_curves.
Figure 17.1. Value gap to the dynamic-programming optimum of the policy learned after a number of episodes (the greedy policy for Q-learning and SARSA, the softmax policy for the others), mean of three seeds. Data: ml_rl.learning_curves.
Ler no capítulo →