Low-Latency Software · Technology
24Resilience
On 1 October 2020, a memory module failed in one of the two devices of a shared disk system inside the Tokyo Stock Exchange’s trading system. Operations “were supposed to switch automatically” to the second device, but the automatic switch did not work for that kind of failure unless a setting had been changed, and it had not. Engineers switched over by hand at 9:26, less than half an hour after the market should have opened, and every function returned to normal. Trading nevertheless stayed halted for the whole day. Orders received before the exchange cut its network had been matched, and their executions had accumulated inside the system without being sent to the participants; only a limited number of participants could have resent their orders, and there were no agreed, tested rules for restarting. The hardware recovered in minutes; the state did not. This chapter is about the second problem: how a trading system keeps one agreed history of what it received and what it sent, so that when a machine fails another can take over in milliseconds without losing an order or sending one twice.
24.1 Failure modes of a trading system
Components fail in a few ways, and each needs a different answer. A process crashes, or its machine does: it stops, and the question is who takes over and from what state. A process hangs or slows down: it has not stopped, so it may come back and act after someone else has taken over, which is worse than a crash. A network link fails: each side may believe the other is dead while both are alive. A venue session drops: the orders at the venue carry on, may fill or may be cancelled by the venue (chapter 21), and the firm does not know which until it reconnects. And the failover machinery itself fails, as in Tokyo, because it runs only when something else has already gone wrong and is therefore the least exercised code in the system. The operational risk of One Quant Book 6 (chapter 28) is, for a trading system, mostly this list.
The design goal follows: every input the system acts on, and every order it sends, must be recorded before it matters, in one order that everyone agrees on, so that any machine can rebuild the state by replaying the record, and any order can be recognised if it is sent again.
24.2 Sequencer architectures
Definition 24.1 (Sequencer architecture)
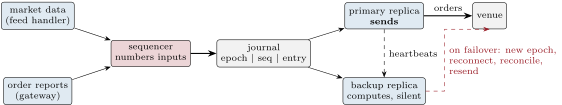
A sequencer architecture is a design in which every input of a system (market events, order reports, commands) passes through a single component, the sequencer, that assigns it the next number of a global sequence and appends it to a durable journal before any other component acts on it; every component then processes the journal in sequence order.
The sequencer turns many unordered sources into one ordered history. It is the input journal of chapter 23 lifted from one process to the system: the market data from the feed handler, the reports from the order gateway, the parameter changes from the control plane all become numbered entries of one journal. The strategy engine’s replay of chapter 23 becomes the normal way of running: a component is a function of the journal, and two components that read the same journal compute the same thing. The cost is one more hop on the path of every input (a microsecond in the build’s simulation, more when the journal is replicated before it is acknowledged), and a component whose own failure must be handled; the retail exchange whose architecture Fowler described (chapter 20) kept its business logic on one thread fed by exactly such a journal, from which its state could be rebuilt.
24.3 Replicated state machines and failover
Definition 24.2 (Replicated state machine, primary–backup replication)
A replicated state machine is a deterministic program run as several copies (replicas) that apply the same sequence of inputs and therefore pass through the same states and produce the same outputs. Primary–backup replication runs one replica as the primary, whose outputs are sent, and others as backups, whose outputs are computed and discarded, ready to replace the primary.
Definition 24.3 (Failover, split brain)
A failover is the replacement of a failed primary by a backup, which takes over its role and its connections. Split brain is the state in which two replicas both act as primary, typically because a backup has taken over from a primary that was slow or cut off rather than dead; each sends outputs the other does not know about.
The state machine approach is old and general (Schneider’s tutorial of 1990), and the hard part of it, agreeing on the next entry of the log when machines fail, is what consensus algorithms such as Raft (Ongaro and Ousterhout, 2014) solve. A trading system usually needs less: one sequencer writing the journal, replicated synchronously to a second machine, and a rule for deciding who is primary. The build’s replicas are the strategy state of the book in miniature: firm.sequencer’s replica trades a hundred shares against every price move with an immediate-or-cancel order, within a position limit, and keeps its orders by an identifier derived from the journal entry that created them. The Python, C++ and Rust replicas replay the fixture’s journal (a failover, with a second epoch, resends and a duplicate in it) to the same states, hash included.
Split brain is prevented by fencing. The journal carries an epoch, a number that only grows; each primary writes under the epoch in which it became primary, and a backup that takes over first raises the journal’s epoch. From then on, the journal refuses any append under an older epoch (Listing 24.1): a primary that was only slow, and wakes up still believing itself in charge, can compute what it likes but can no longer record anything, and nothing it has not recorded is sent. The gateway enforces the same rule on outputs, since the venue does not know about epochs.
    // The sequence number of the new entry; throws if the writer's epoch has been fenced off.
    std::int64_t append(Entry e) {
        if (e.epoch < epoch_) throw std::runtime_error("fenced: an older epoch cannot append");
        e.seq = static_cast<std::int64_t>(entries_.size()) + 1;
        entries_.push_back(e);
        return e.seq;
    }
    void fence(std::int64_t epoch) {
        if (epoch <= epoch_) throw std::runtime_error("a new epoch must be larger");
        epoch_ = epoch;
}Failure is detected by heartbeats: the primary sends one every millisecond, and the backup declares it dead after three missed. Detection is therefore the largest part of the build’s recovery time: 2.8 to from the failure to a backup that is primary, reconnected and reconciled, of which the reconnection and the replay of the missed reports take tens of microseconds. A shorter timeout recovers faster and declares more slow primaries dead, which is exactly when fencing matters. The backup in the build is hot: it applies every journal entry as it is written, so there is nothing to catch up. A cold backup must replay the journal first; the C++ replica applies it at about an entry, so a day’s journal of 37 million entries (chapter 23) takes about a second and a half, acceptable for a restart and not for a failover.
24.4 Exchange disconnects and recovery
Definition 24.4 (Idempotent processing)
An operation is processed idempotently if doing it twice has the same effect as doing it once. For orders, it means that every order carries an identifier fixed when it is created, so that the venue, or the firm’s own gateway, recognises a second copy and discards it.
The dangerous moment of a failover is the orders in the gap: those the old primary sent whose reports were never journaled. The new primary knows they exist, since it computed them from the journal, but not whether they left: the old primary may have died before sending, while the order was on the wire, or after the venue executed it and before the report came back. It has three ways to proceed (Listing 24.2). It can resend them at once under fresh identifiers, the habit of gateways that never reuse an identifier. It can first log in again, ask the venue for the reports it missed (the sequenced replay of chapter 21), reconcile, and resend only what is still unaccounted for. Or it can resend at once under the orders’ original identifiers, derived from the journal, and let the venue reject any copy of an order it already has.
    def takeover(t):
        state["leader"], state["took_over"] = "backup", t
        state["epoch"] += 1
        journal.fence(state["epoch"])
        pending = backup.unacknowledged()
        if procedure == "fresh ids, reconciled":
            push(t + 2 * WIRE_NS, "login")                # replay first; resend after it (see "login")
            return
        for i, (key, cl) in enumerate(pending):
            resend(t, key, cl, i)
        push(t + 2 * WIRE_NS, "login")

    def resend(t, key, cl, i):
        o = backup.open[cl]
        out.resent += 1
        if procedure == "idempotency keys":
            send(t, cl, o.side, o.qty, o.price)
        else:
            new = 10**9 * state["epoch"] + i + 1
            journal_append(t, "A", key[0], key[1], new)
            key_of_cl[new] = key
send(t, new, o.side, o.qty, o.price)Table 24.1 kills the primary at every stage of every one of the scenario’s 46 orders, against Book 10’s matching engine. With fresh identifiers and no reconciliation, a failure while an order is on the wire or at the venue but not yet reported sends it twice: 54 of the 184 cut points end with a duplicate, one for each of the 27 orders that filled, in each of the two stages, and the worst push the position past its limit, to 1 100 shares against 1 000. Reconciling first removes them all in this model, because every order is reported within and the venue replays its reports. Idempotent identifiers remove them regardless of the order of operations, which matters when the venue is slow to report or the session cannot be replayed: the participants of the Tokyo exchange in 2020 were in exactly that position. In every case the new primary’s state equals a fresh replay of the journal and the position the venue holds.
| procedure | duplicates, by stage of the order at the failure | largest position | |||
| journaled | in flight | at the venue | reported | ||
| fresh identifiers | 0 | 27 | 27 | 0 | 1 100 |
| fresh identifiers, reconciled first | 0 | 0 | 0 | 0 | 1 000 |
| idempotency keys | 0 | 0 | 0 | 0 | 1 000 |
fig_failover.py (deterministic).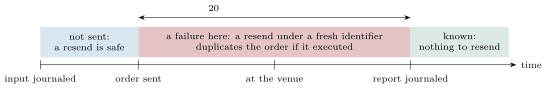
The same reasoning applies to a simple disconnect, without any failover: the gateway loses its session, logs in again asking for the reports it has not seen, applies them (the venue’s cancel on disconnect may have cancelled resting orders meanwhile), reconciles against the drop copy, and only then lets the strategy trade. Book 10’s simulator provides each piece: sequenced replay on login, cancel on disconnect, and the rejection of a duplicate client order identifier.
24.5 Testing failover
Failover code runs when something else has already failed, so it is the least tested code in a system unless it is tested on purpose, and the Tokyo incident is the standard example of a switch that worked for the failures it was tested against and not for the one that happened. The build’s test is the table: the primary is killed at every stage of every order of a scenario, and each run is checked against properties that must hold whatever the failure point (the new primary’s state equals a replay of the journal; its position equals the venue’s; no order is executed twice when idempotency keys are used). The properties matter more than the scenario; exhaustive cut points turn a rare event into a routine test. In production, the same idea is practised by failing over deliberately, on a schedule, so that the procedure is exercised when nothing else is wrong.
24.6 Tutorial: kill the primary everywhere
Goal. Run the sequencer, two replicas and a gateway against the matching engine, kill the primary at every stage of every order, and compare three recovery procedures. End state: Table 24.1, and green replays of the failover journal in three languages.
- The scenario.
firm_sequencer_sim.run(None)runs 60 prices, a millisecond apart, without failure: 46 orders, a position of , the state equal to a replay. - Cut points.
cut_points()lists the middle of each of the four stages of each order;python fig_failover.pyruns the three procedures at each. - Replicas in three languages. The C++ and Rust replicas replay
data/journal.txt, a failover with fresh identifiers, and reach the states ofdata/expected.txt; a writer from the old epoch is refused. - Catch-up.
python bench_sequencer.pytimes a replica applying two million entries.
What to change next. Delay the venue’s reports by a millisecond and watch duplicates appear with reconciliation too; shorten the heartbeat timeout and count the failovers a slow primary would cause.
24.7 Build: the sequencer
Purpose. The backbone that makes the trading path of the book (chapters 18 to 22) restartable and replicable: one journal of numbered inputs, replicas that compute from it, and a failover that neither loses nor duplicates an order.
Interface. Python reference firm_sequencer: Journal with append and fence; Replica with apply and unacknowledged; cl_for; to_line, from_line; firm_sequencer_sim.run and cut_points against Book 10’s engine. C++20 firm::seq: Journal, Replica, parse. Rust firm_sequencer: Journal, Replica, parse.
Rules. Nothing acts on an input before it is journaled; replicas are deterministic functions of the journal; epochs only grow and fence older writers; order identifiers derive from the journal; resends are journaled.
Acceptance tests. code/firm/sequencer/: the failover journal replayed to the same states in three languages; fencing refuses an old epoch; gaps refused; at every cut point of the scenario and for each procedure, the state equals a replay and the venue’s position; duplicates only with fresh identifiers and without reconciliation.
Stretch. A replicated journal with synchronous acknowledgement by the backup; several gateways behind the replicas; Raft for electing the primary; the gateway of chapter 21 and the risk gate of chapter 22 as replicas.
Sources and further reading
- Tokyo Stock Exchange, The Cause of the Recent Failure in arrowhead and Measures Implemented, 5 October 2020, and The Failure of Equity Trading System on October 1, 2020, report, 19 October 2020.
- F. B. Schneider, “Implementing fault-tolerant services using the state machine approach: a tutorial”, ACM Computing Surveys 22(4), 1990.
- D. Ongaro and J. Ousterhout, “In search of an understandable consensus algorithm”, USENIX Annual Technical Conference, 2014.
24.8 Exercises
Exercise 24.1 ★
The journal’s epoch is 3. The old primary, which became primary in epoch 2, tries to append. What happens, and what happens to the orders it computed from that entry?
Solution
Solution of Exercise 24.1.
The journal refuses the append: epoch 2 is older than 3. The entry is not recorded, so no replica applies it, and the orders the old primary computed from it are never sent, since only journaled outputs are sent (and the gateway checks the epoch too).
Exercise 24.2 ★
Heartbeats every millisecond, three missed declare the primary dead, checked at each heartbeat tick. What are the shortest and longest times from a failure to its detection?
Solution
Solution of Exercise 24.2.
The last heartbeat was sent at some tick before the failure. Death is declared at the first tick at or after ms: if the failure came just after , detection takes almost ; if it came just before the next tick, a little over . Hence the build’s recovery times of 2.8 to , reconnection included.
Exercise 24.3 ★
An order created by journal entry 46 is the first output of that entry. What is its client order identifier in the build, and why must every replica compute the same one?
Solution
Solution of Exercise 24.3.
. Every replica must derive it from the journal so that reports, which name the order by this identifier, are applied to the same order everywhere, and so that a resend under it is recognised by the venue as a copy.
Exercise 24.4 ★★
A strategy sends 500 orders a second; each spends between leaving and having its report journaled, and 90% of them execute. A failure happens at a random moment. What is the probability that a fresh-identifier resend without reconciliation duplicates an order?
Solution
Solution of Exercise 24.4.
.
Exercise 24.5 ★★
A cold backup applies the journal at an entry. How long does it take to catch up on a day of 37 million entries, and on the last hour of it? Why keep the backup hot anyway?
Solution
Solution of Exercise 24.5.
for the day, about for its last hour. A hot backup needs no catch-up at all, and it has been exercised on every entry: a cold one is replaying code paths at the worst moment.
Exercise 24.6 ★★
The venue rejects a copy of an order under an identifier it has seen. The backup resends under original identifiers an order the venue executed. What does the backup receive, and what must its replica do with it?
Solution
Solution of Exercise 24.6.
A rejection with reason D (duplicate identifier), journaled like any report. The replica keeps the order open (the venue has the original) and waits for the original’s reports, which the session’s replay delivers; it must not treat the rejection as the end of the order.
Exercise 24.7 ★★★
Coding. Delay the venue’s reports by a millisecond in firm_sequencer_sim and rerun the three procedures. Which one now duplicates orders, at which stages, and why do idempotency keys still produce none?
Solution
Solution of Exercise 24.7.
With reports delayed, orders are still unreported when the backup takes over, even after its replay: “fresh identifiers, reconciled” now resends them too, and duplicates those that the venue has already executed, at the stages “sent” and “at the venue”. Idempotency keys still produce none, because the venue recognises each copy by its identifier whatever the backup knows.
Exercise 24.8 ★★★
Find the flaw. “Our failover is simple: the backup watches the primary’s heartbeat, and when it stops, the backup restarts the strategy from its configuration and sends new quotes.”
Solution
Solution of Exercise 24.8.
Restarting from the configuration forgets the state: the position, the open orders at the venue, the orders in flight. The new quotes are sent next to the old ones, which may still be live (unless cancel on disconnect removed them), and the position limits are checked against a position of zero. The backup must rebuild the state from the journal, reconnect, reconcile, and only then trade; and if the primary was only slow, nothing stops it from sending too: there is no fencing.
24.9 Problem: The Failover That Doubled the Orders
Problem 24.1
Weekend problem — counting duplicates over every point of failure
Use Table 24.1 (failover.csv, failover_summary.csv): 46 orders in 60 milliseconds, four stages each, three recovery procedures.
Part I — The window.
- Name the four stages of an order’s life used as cut points, and say for which of them the new primary cannot tell whether the order left.
- How long does an order spend in the two dangerous stages in the simulation?
- Why do only 27 of the 46 orders produce a duplicate in each dangerous stage?
- Why does a failure while an order is journaled but not yet sent never duplicate it?
Part II — Over time.
- What is the scenario’s order rate?
- If the failure time is uniform over the scenario, what is the probability that a fresh-identifier failover duplicates an order?
- What would it be for a strategy sending 5 000 orders a second with the same latencies?
- Why does the largest position reach 1 100 with fresh identifiers?
Part III — The remedies.
- Why does reconciling first remove every duplicate in this model?
- Give two real situations in which reconciling first would not be enough.
- Why do idempotency keys work whatever the order of operations?
- What must hold for idempotency keys to be possible at all?
Part IV — The verdict.
- State the named result: duplicates after a failover without idempotency keys over the failure points, with them, and the recovery time.
- What dominates the recovery time, and what is the price of shortening it?
- What does fencing add that idempotency keys do not?
- What went wrong in Tokyo in 2020, in the chapter’s terms?
- Why must the resends themselves be journaled?
- Which properties does the test check at every cut point, and why properties rather than expected outputs?
- What would you add to test a cold backup?
- In one sentence: what makes a failover safe?
Solution
Solution of Problem 24.1.
- Journaled but not yet sent; sent and in flight; at the venue but not yet reported; reported. The new primary cannot tell, in the second and third, whether the order left.
- on the wire, then until the report is journaled: .
- A duplicate counts only if both copies executed; the other 19 orders found no liquidity at their limit and were cancelled (immediate or cancel), so their copies were cancelled too.
- The primary had not sent it, so the backup’s resend is the only copy.
- orders a second.
- The dangerous windows add up to in : about 1.8%.
- .
- The duplicate adds a second execution to a position the replica had already brought to its limit of 1 000.
- The venue reports every order within and replays its reports on login, so after the replay nothing sent is unaccounted for.
- A venue that reports slowly (a resting order acknowledged late, a busy matching engine), or a session that cannot be replayed (a new session, a venue without sequenced replay, the situation of the Tokyo participants in 2020).
- The venue recognises the copy by its identifier; it does not matter what the new primary knows or in what order it acts.
- Identifiers fixed when the order is created, derived from something every replica agrees on (the journal), and a venue or gateway that rejects a reused identifier within the session.
- Named result. Without idempotency keys and without reconciliation, a failover duplicated an order at 54 of the 184 cut points (every executed order, whenever the failure fell between its departure and its report), about 1.8% of failures at a random time in the scenario, pushing the position to 1 100 against a limit of 1 000; with idempotency keys, none; and recovery took 2.8 to , almost all of it the heartbeat timeout.
- The heartbeat timeout; shortening it declares slow primaries dead more often, which makes fencing indispensable.
- It stops a primary that is not dead from recording and sending anything after the takeover; idempotency keys stop copies of the same order, not new orders from a second primary.
- The failover (the switch to the second device) failed for an untested kind of failure; after the manual switch, the state of the orders was not agreed between the exchange and its participants, and there was no tested procedure to reconcile and restart.
- So that every replica agrees on which identifier each order now has; otherwise a later failover would not know about the resend.
- State equal to a fresh replay of the journal, position equal to the venue’s, no execution twice with keys. Properties hold whatever the failure point, so one check covers all 184 runs, and they say what correct means rather than what one run did.
- Kill the backup’s state first, restart it from the journal at every cut point, and check the same properties plus the catch-up time.
- One journal that every replica follows, identifiers derived from it, fencing of the old primary, and reconciliation before trading resumes.
24.10 Interview questions
Interview question 24.1 ★ developer
What is a sequencer, and why would a trading system put one in front of everything?
Solution
Solution of Interview question 24.1.
A single component that numbers every input and journals it before anyone acts on it. It gives the system one order of events, so that components are deterministic functions of the journal: they can be replicated, replayed and restarted.
What the interviewer is looking for: total order, journal, determinism.
Interview question 24.2 ★★ developer
Your primary stops sending heartbeats. How does the backup take over without sending duplicate orders?
Solution
Solution of Interview question 24.2.
It is hot (has applied the journal), so it fences the old primary with a new epoch, reconnects the venue session asking for the missed reports, applies them, and resends the orders no report acknowledges under their original, journal-derived identifiers, so that the venue rejects any copy.
What the interviewer is looking for: fencing, replay of reports, idempotent identifiers.
Interview question 24.3 ★★ developer
What is split brain, and how do you prevent it?
Solution
Solution of Interview question 24.3.
Two replicas acting as primary at once, usually after a takeover from a primary that was slow rather than dead. Prevent it with fencing (an epoch that only grows, checked by the journal and the gateway) and, for electing the primary, a quorum.
What the interviewer is looking for: epochs and quorum.
Interview question 24.4 ★★ developer, trader
Your session to the exchange drops for five seconds. What do you do, in order, when it comes back?
Solution
Solution of Interview question 24.4.
Stop the strategy’s new orders; log in asking for the reports missed; apply them; account for cancel on disconnect; reconcile the open orders and position against the drop copy; resend or cancel what is unaccounted for with idempotent identifiers; then resume.
What the interviewer is looking for: replay, reconcile, then trade.
Interview question 24.5 ★★ developer
How would you test that failover works, given that it is needed rarely?
Solution
Solution of Interview question 24.5.
Make failure a routine test: kill the primary at every cut point of scenarios in continuous integration and check properties (state equals replay, positions equal the venue’s, no duplicate); fail over in production on a schedule.
What the interviewer is looking for: exhaustive cut points, properties, scheduled failovers.
Interview question 24.6 ★★★ developer
Design a trading system that survives the loss of any one machine with at most a few milliseconds of interruption and no lost or duplicated order. What are the components, the protocol between them, and the tests?
Solution
Solution of Interview question 24.6.
A replicated sequencer and journal; hot replicas of the engine, the risk gate and the gateway as deterministic functions of it; primary election with epochs; heartbeats with a timeout of a few milliseconds; sessions with sequenced replay and idempotent identifiers; reconciliation against drop copies. Tested by killing each machine at every cut point of recorded days.
What the interviewer is looking for: journal, replicas, fencing, idempotency, tests.